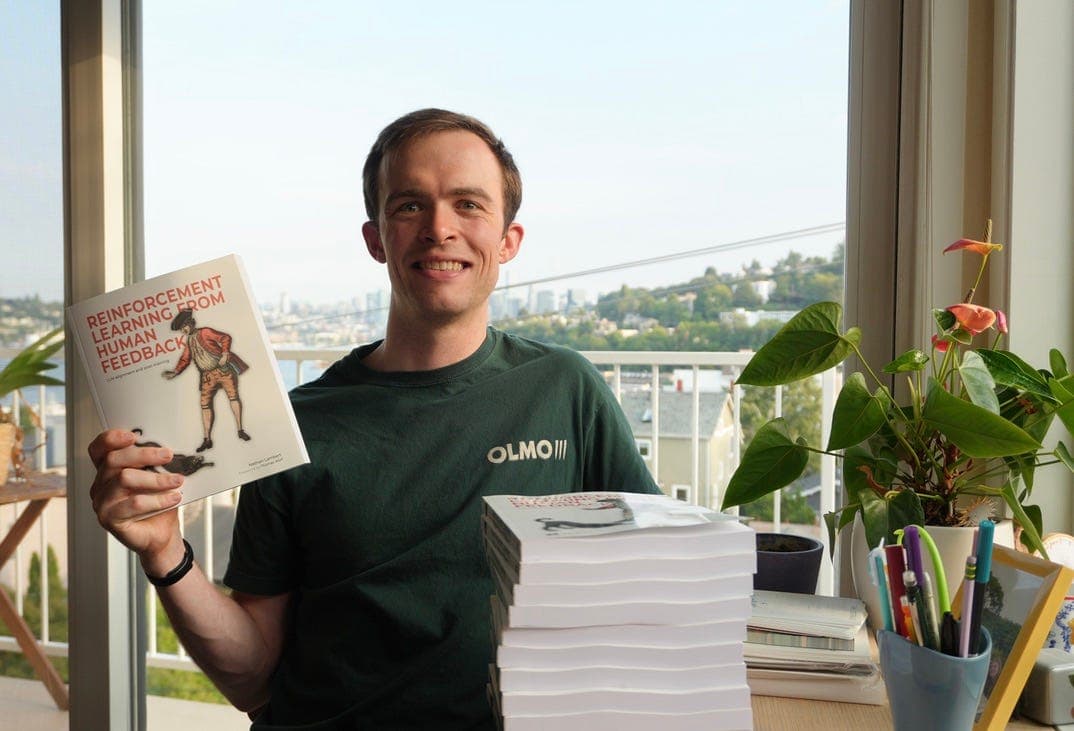
Nathan Lambert's post-training textbook, 'Reinforcement Learning from Human Feedback: Aligning and Post-training LLMs,' published by Manning, is now shipping. The book covers territory that has been genuinely underdocumented: rejection sampling, outcome reward models, and character training are all treated here at a foundational level. The website it grew from, rlhfbook.com, became popular precisely because no comparable resource existed. That gap is real, not marketing.
About 25% of the book is pure RL, covering the policy-gradient theorem through PPO and into modern variants like GSPO and CISPO. The PPO clipping section alone, which reduces the surrogate objective to six interpretable regions mapped against the policy ratio, is worth reading carefully. This is the kind of intuition that tells you whether a new algorithm has legs before any benchmarks exist. The book assumes a CS bachelor's degree and does not apologize for it.
The full text is free at rlhfbook.com. A 12-hour course with slides and YouTube video accompanies it, along with a code repository and model completion comparisons. The Manning print edition is 50% off through August 19 with code PBLambert. The UK Amazon edition ships in October. Read the original post for the remaining four takeaways Lambert outlines, including the sections on reward models and the last-minute addition on on-policy distillation.
[READ ORIGINAL →]